Proof: what we ran
We synced a mainnet node in 14 h 06 m, posted a cast through it, and deleted the server 70 h 04 m after renting it.
We ran the 3 steps once, on mainnet, on 2026-10-18. Times are IST (UTC+5:30). The server was a Hetzner cax31 (ARM64, 8 vCPU, 16 GB RAM) in fsn1 with a 1000 GB volume and Ubuntu 24.04. The node ran Snapchain v0.14.3. The full notes are in MEASUREMENTS.md and run-log.md. We replaced the server’s IP, its Hetzner IDs and our test account with placeholders before publishing them.
The run, start to finish
Section titled “The run, start to finish”| Event | Date and time (IST) |
|---|---|
Server rented with provision.sh | 2026-10-18 01:26 |
| Node fully synced, every shard less than 10 s behind | 2026-10-18 15:32 |
| Cast posted through the node | 2026-10-18 20:53 |
Server and volume deleted with teardown.sh | 2026-10-20 23:30 |
The server ran for 70 h 04 m. From 15:32 on 2026-10-18 until shutdown, all 3 shards stayed at the tip. The last count, at 22:56 on 2026-10-20, was 914,276,853 messages in a 558 GB database. The run cost $11.49 (Cost). After teardown.sh the Hetzner project was empty. The screenshots on this page are from 2026-10-18.
Posted to mainnet
Section titled “Posted to mainnet”On 2026-10-18 we added an app key to our own Farcaster account and posted a cast through our node.
| What | Time (IST) |
|---|---|
Gasless KEY_ADD accepted: signer source OFFCHAIN, scopes CAST_ADD, REACTION_ADD and LINK_ADD, 1-day expiry, nonce 1 | 20:53:29 |
| Cast confirmed by the node | 20:53:47 |
The cast says “My first cast on a local node”. Hash 0x4b4eb31bb28cf0d6d0583c7fc022a60f0af50ec2. See the cast.
The cast was confirmed 18 seconds after the key. The app ran on localhost on our own computer (client commit 7f2b71f), with SNAPCHAIN_NODE_URL pointing at our node through Caddy. We typed the recovery phrase into that browser tab. It never left the browser: only the signed KEY_ADD and the cast went to the node. We have not sent a like, recast or follow on mainnet.
The sync, from the log
Section titled “The sync, from the log”A logger on our side read the disk and the node’s /v1/info over SSH every 10 minutes. Some of its lines, with the memory and status fields cut:
01:38:17 IST progress: du=1.1G df=1% Progress: 14/5689 chunks (0%) (ETA: 4h50m) info=none03:13:11 IST progress: du=139G df=15% Progress: 1705/5689 chunks (29%) (ETA: 3h43m) info=none08:37:12 IST progress: du=494G df=53% Progress: 5319/5689 chunks (93%) (ETA: 0h28m) info=none12:41:33 IST progress: du=556G df=60% info=[{"s":0,"h":48251171,"d":45482},{"s":1,"h":48946704,"d":24543},{"s":2,"h":48763546,"d":43641}]15:32 IST synced: /v1/info shard 0 h=48305951 blockDelay=1, shard 1 h=48980989 d=1, shard 2 h=48816538 d=416:20:25 IST progress: du=556G df=60% info=[{"s":0,"h":48308772,"d":4},{"s":1,"h":48983812,"d":1},{"s":2,"h":48819359,"d":0}]h is a shard’s block height and d its blockDelay, in seconds behind. At 12:41 shard 0 was still 45,482 seconds (12 h 38 m) behind. At 15:32 every shard was within 4 seconds: that is the sync time in the table below. At 16:20 it was still at the tip.
The sync phase times below come from a logger that read every 10 minutes, so each is accurate to 10 minutes.
| Phase | Time |
|---|---|
provision.sh | 35 s (started 01:26:33) |
| Snapshot download | 5 h 24 m for 5689 chunks, 485 to 505 GB by our disk readings, 25 to 26 MB/s |
| Snapshot load in total (download, gunzip, untar, shard by shard) | 8 h 34 m |
| Catching up after the load | 5 h 15 m, at 4.3 to 4.6 blocks a second per shard |
| From renting the server to fully synced (every shard less than 10 s behind) | 14 h 06 m |
deploy-client.sh, including the Let’s Encrypt certificate | 35 s, measured once |
Problems we hit on the way, all on 2026-10-18, IST. Each has a fix on Fix a problem:
| Time | What happened |
|---|---|
| 01:20 | cx43 was not available to rent, so we rented cax31 |
| 01:23 | The 2000 GB volume went over the new-account limit; we used 1000 GB |
| 01:35 | SSH was refused: the machine running the steps kept getting new public IPs, so the firewall no longer matched |
| 01:44 | The disk was filling during the restore; we installed the two disk helpers by hand |
| 01:38 to 10:11 | The HTTP API did not answer while the snapshot loaded |
| 13:39 | node.sh stopped waiting at its old 12-hour limit; the node kept syncing |
| 18:48 | cax31 was not available to rent in fsn1, nbg1 or hel1 when we checked |
| Whole sync | The computer running the steps paused at least 13 times; the node kept going |
The node once synced
Section titled “The node once synced”| Item | Value | Measured with |
|---|---|---|
| Database | 557.86 GB. Per shard on disk: 37, 261 and 259 GiB | /v1/info dbStats.approxSize, du -sh |
| Messages | 914,243,963 messages and 3,355,148 FID registrations | /v1/info |
| Disk | 557 GB used, 378 GB free (60%) of 984 GB | df -h |
| Fullest the disk got | 699 GB (75%), during the shard 2 unpack, with snapshot-space-saver.sh running | the 10-minute logger, so the real peak may be higher |
| Memory on the server | 2.4 to 2.6 GiB used and 12.7 GiB available; most of the rest was file cache | free -m |
| Memory per container | snapchain 1.53 GiB, statsd 264 MiB, Grafana 68 MiB, Caddy 12 MiB | docker stats |
| CPU | snapchain 1.3% in one reading once synced; load average 0.7 to 1.5 on 8 vCPU | docker stats, /proc/loadavg |
| Peers | 5, all mainnet validators | /v1/mesh, read on the server |
| Read time through Caddy | 0.2 s per /v1/* request, rounded to 0.1 s | curl |
| Item | Amount |
|---|---|
| Price | $0.164 an hour: cax31 $0.040, IPv4 $0.001, 1000 GB volume $0.123 (our estimate: $76.70 a month ÷ 625 hours) |
| Until synced, 14 h 06 m | $2.31 |
| Whole run, 70 h 04 m (2026-10-18 01:26 to 2026-10-20 23:30) | $11.49 |
| Left running | $102.29 a month: $24.99 + $0.60 + $76.70, the monthly prices Hetzner stops at |
| Invoice | Not arrived yet. The amounts above are estimates from Hetzner’s hourly price. |
The official AWS guide estimates “roughly $100/month”; that is an estimate, not a run.
Not measured: how long a valid message takes to show up, Grafana’s peak memory, and what happens over days with inbound 3382/udp closed. A 2-minute test with it closed kept all 5 peers.
The app on the synced node
Section titled “The app on the synced node”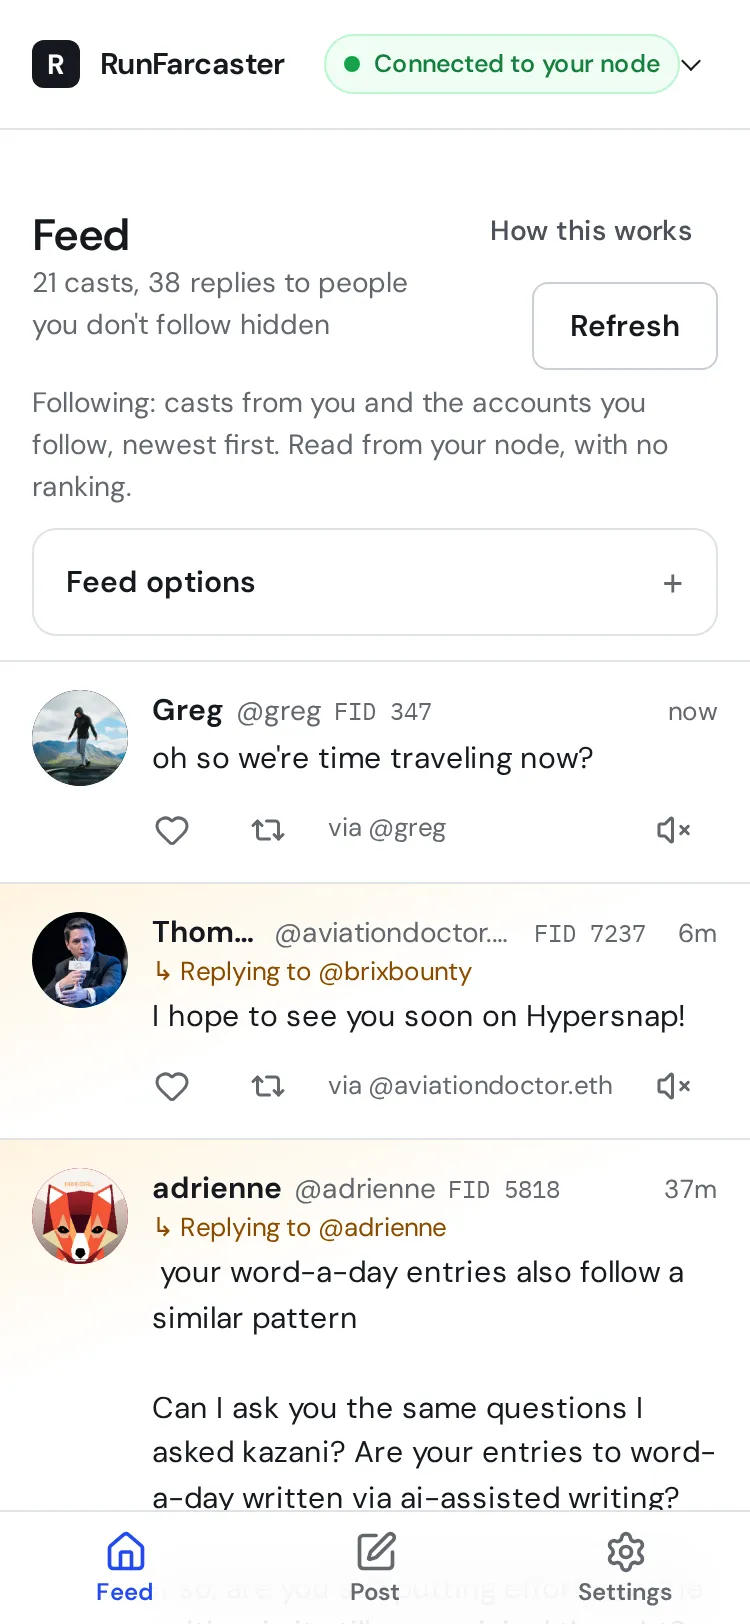
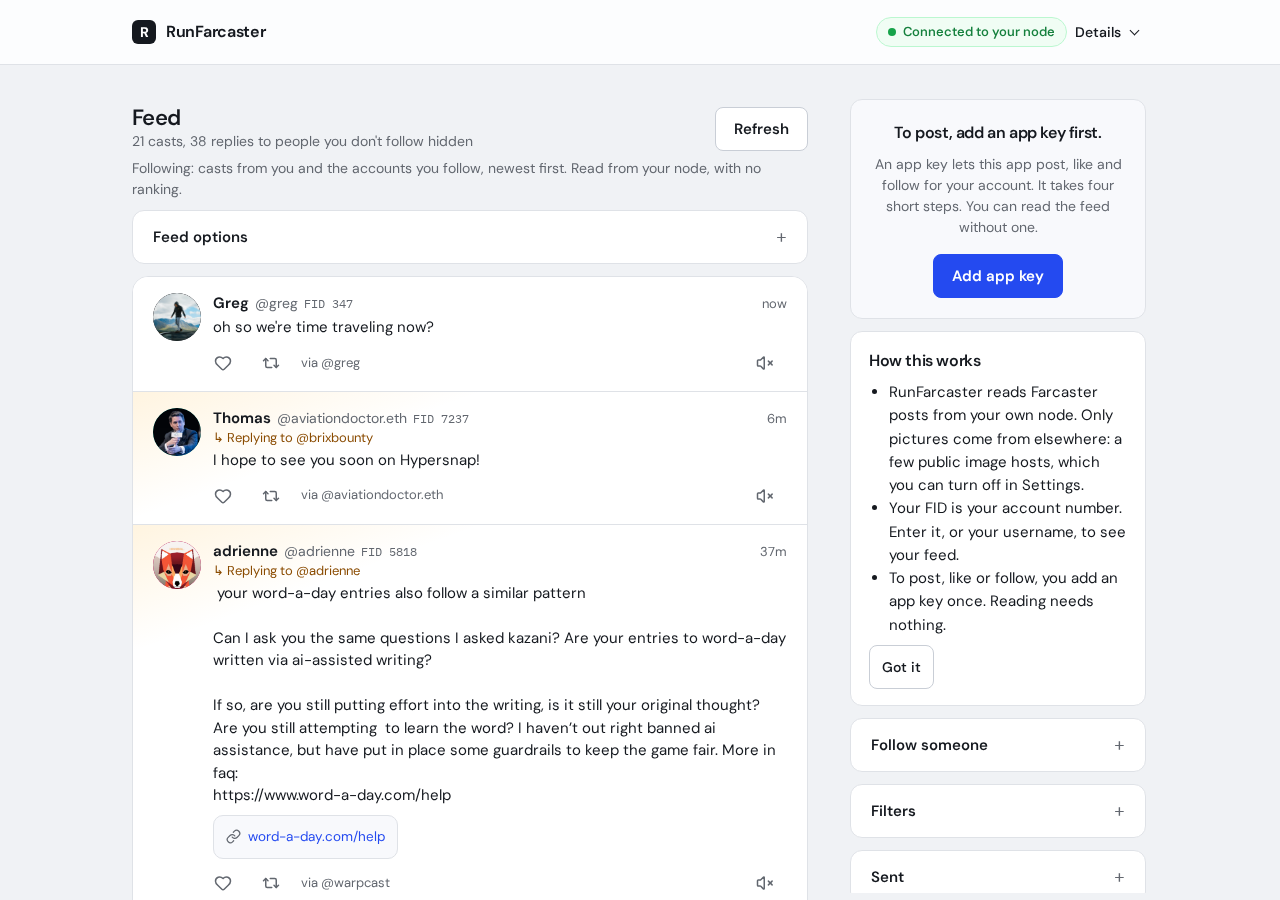
Taken in Chrome against the live node on 2026-10-18 at 22:38 IST, after the app’s last layout change (client commit 9b4764c, 22:15 IST).
Test status
Section titled “Test status”| What | Status | Evidence |
|---|---|---|
provision.sh on Hetzner (cax31, VOLUME_GB=1000) | Ran live | 35 s |
node.sh: official bootstrap, full mainnet sync, health check, second run skips the bootstrap | Ran live | Sync timeline below |
deploy-client.sh: Caddy, Let's Encrypt, /v1 on the same address | Ran live | HTTPS 200 with CSP and HSTS headers |
| App reads on the real node (feed, filters, mute, key and storage lookups, 360 and 375 px layout) | Ran live, read-only | e2e/real-node.mjs: 17 of 17 |
| Node rejects a broken message | Ran live | HTTP 400 "Invalid protobuf data" |
disk-guard.sh and snapshot-space-saver.sh, installed by hand | Ran live | The saver deleted used chunks and tars; its hole-punching had no effect. Disk peaked at 75%, so the guard never fired. |
node.sh installing those two helpers by itself (new) | Unit tests only | test/node_sh_test.sh; not yet used in a live sync |
watchdog.sh | Ran live (old version); new progress check unit-tested | $3.17 spent of the $5 cap when we turned it off at 20:49 IST on 18 Oct 2026 to keep the node up; test/watchdog_test.sh |
provision.sh starting the watchdog by itself (new) | Unit tests only | test/provision_test.sh; in our run we started it by hand |
Gasless KEY_ADD on mainnet | Ran live once | Added 20:53:29 IST on 18 Oct 2026; 1-day key, signed in the browser on localhost |
| Cast on mainnet | Ran live once | Confirmed 20:53:47 IST; see Posted to mainnet |
| Like, recast, follow on mainnet | Not tried | Unit tests and a local mock node only |
| Time from sending a message to seeing it | Not measured precisely | One cast: 18 s from key added to cast confirmed |
teardown.sh against real servers | Ran live once | Deleted the server, volume and firewall at 23:30 IST on 20 Oct 2026; the project was empty afterwards |
| 2 TB volume, x86 (cx43) server | Not tried | Volume quota; cx43 was not available to rent in fsn1 on 18 Oct 2026 |
| Running with inbound 3382/udp closed | 2-minute test | Still 5 peers; long-term effect unknown |
Test results
Section titled “Test results”| Suite | Result | What it covers |
|---|---|---|
e2e/real-node.mjs on the live node | 17 of 17 | Listed below the table |
e2e/run.sh (the real Caddyfile, a mock node, headless Chrome) | 72 of 72 | The same app and proxy on one machine: CSP headers and <meta>, the add-app-key steps, a signed key and cast, feed rules, filters by app, pictures on and off, phone and desktop layout, error states |
Client unit tests (vitest) | 69 of 69, 9 files | Messages, key adding, feed, filters, timeline, retry logic, formatting, the app behind each cast |
test/node_sh_test.sh | 42 of 42 | Sync rules, bootstrap under a fake terminal, .env answers, the new disk-helper install and re-run |
test/space_saver_test.sh | 14 of 14 | Chunk and tar clean-up, hole punching, waiting for the snapshot folder |
test/watchdog_test.sh | 16 of 16 | Progress check during a sync, a stuck node, SSH loss, money cap, macOS without timeout, a missing token written to the log |
test/teardown_test.sh | 9 of 9 | Running twice, missing token, wrong confirmation, a server ID that differs from the one provision.sh recorded |
test/provision_test.sh | 29 of 29 | SSH_SOURCE_CIDRS check, the watchdog start (with a stand-in watchdog), no second watchdog, a loud stop when it cannot start, unavailable server types and the SERVER_TYPE="" auto-pick, a server or firewall left from an earlier run, the volume quota (with a fake hcloud) |
shellcheck | No warnings | Every shell script |
We ran the shell suites, shellcheck, the client unit tests and e2e/run.sh on 2026-10-21 at 00:03 IST, on commit 3e06969. e2e/real-node.mjs ran on 2026-10-18 against the live node, last at 18:07 IST, and can’t be rerun now that the server is deleted.
What e2e/real-node.mjs checked:
- HTTPS with CSP
connect-src 'self'and HSTS. - Status
Connected(v0.14.3). - 21 real casts in the feed.
- Mute by FID hides casts, and the mute survives a reload.
- Key and storage lookups.
/v1/meshreturns 404.- A broken
submitMessagereturns 400. - No third-party or mixed-content requests.
- No key or phrase in browser storage.
- No sideways scroll at 375 px or 360 px.
- No console errors or CSP violations.
The live run used the earlier versions of node.sh, watchdog.sh and the firewall rules. Commands to rerun the suites:
shellcheck -x -P SCRIPTDIR *.sh test/*.sh e2e/*.shbash test/node_sh_test.shbash test/space_saver_test.shbash test/watchdog_test.shbash test/teardown_test.shbash test/provision_test.sh(cd client && npm ci --ignore-scripts && npm run typecheck && npm test)(cd e2e && npm ci && CADDY=caddy CHROME=/path/to/chrome ./run.sh)SITE=https://<name> CHROME=/path/to/chrome node e2e/real-node.mjse2e/real-node.mjs never pastes a phrase, never creates a key, and never presses Cast, Like, Recast or Follow.
Independent test
Section titled “Independent test”Tester Nick ran RunFarcaster on his own Hetzner cax31. Shard 0’s snapshot was replaced mid-download, and the node crashed on a 404. He fixed it by hand with the steps ./node.sh repair-shard 0 automates, and the node synced fully about 3 h later. His report on the Snapchain repo.
Vouches
Section titled “Vouches”We are asking at least one other person to run the guide on their own account and post the result on Farcaster.
Nick (@otterly), Oct 22, 2026. Ran the Full run on his own Hetzner cax31 (commit a608c66). It synced 914M messages in 19 h 23 m, for $3.30 by his count, and then he deleted the server. Posting wasn’t tested. Read his vouch.
How to vouch
Section titled “How to vouch”The checklist is in VOUCHER.md. In short:
- Note the commit you used:
git rev-parse --short HEAD. - Complete the Full run. Write down how long renting the server and the sync took, what Hetzner charged, the server type and the volume size.
- Open the app from your node and check that a feed loads.
- Optional, with a test account only: add an app key and send one cast (Post with an app key). Note the cast hash and whether another app shows it.
- Run
teardown.shand check in the Hetzner console that the project is empty. - Post what happened on Farcaster, including anything that broke.
Leave your recovery phrase, Hetzner token and server details out of the post.